
How can staggering email sends improve sender reputation and avoid throttling?

Published 11 Jun 2025
Updated 11 Oct 2026
12 min read
Summarize with
Updated on 11 Oct 2026: We updated our sending guidance for shared rate limits, retry handling, recipient suppression, and Gmail spam-rate targets.
Staggering email sends helps protect sender reputation by turning a sharp volume spike into controlled waves that reduce the risk of mailbox-provider rate limiting. It supports steadier sending volume and gives you time to assess successful delivery, recipient response, complaints, and bounces. It also gives you time to slow or stop sending to an affected provider before temporary deferrals accumulate.
Staggered sending gives you control over delivery speed. If recipients do not want the message, pacing will not make it wanted. When the message has a legitimate reason to be sent, pacing reduces abrupt changes in sending behaviour and creates time to act on early delivery signals.
- Predictable volume avoids a sudden burst from an IP or domain.
- Staggering weak mail only slows the damage if the list has stale users, high complaints, high bounces, or broken authentication.
- Use staggered sending for large notices, monthly newsletters, seasonal volume increases, IP warmup, and provider-specific recovery.
Why staggered sending works
Mailbox providers evaluate actual sending behaviour and recipient response, not the sender's internal campaign label. A message labelled transactional can still affect reputation when it generates complaints, hard bounces, authentication failures, or consistently weak engagement. That matters when a team wants to send a required notice to millions of old users who have not interacted for months.
A sudden spike creates several problems at once: connection pressure, higher retry volume, more mailbox-provider scrutiny, and a larger sample of disengaged recipients in a short window. If the provider sees weak results during that window, it can defer, throttle, route to spam, or harden limits for the next wave. That is why volume fluctuations matter so much.
All at once
- A single spike gives providers little time to assess quality before limits trigger.
- Deferrals and soft bounces pile up quickly, then retries add more pressure.
- By the time you notice provider-specific throttling, most mail is already queued.
Staggered
- Small waves keep sender behaviour steady across hours or days.
- Separate queues let you respond to provider-specific deferrals, while shared IP or domain issues still affect multiple queues.
- You can pause low-performing segments and keep healthy lanes moving.
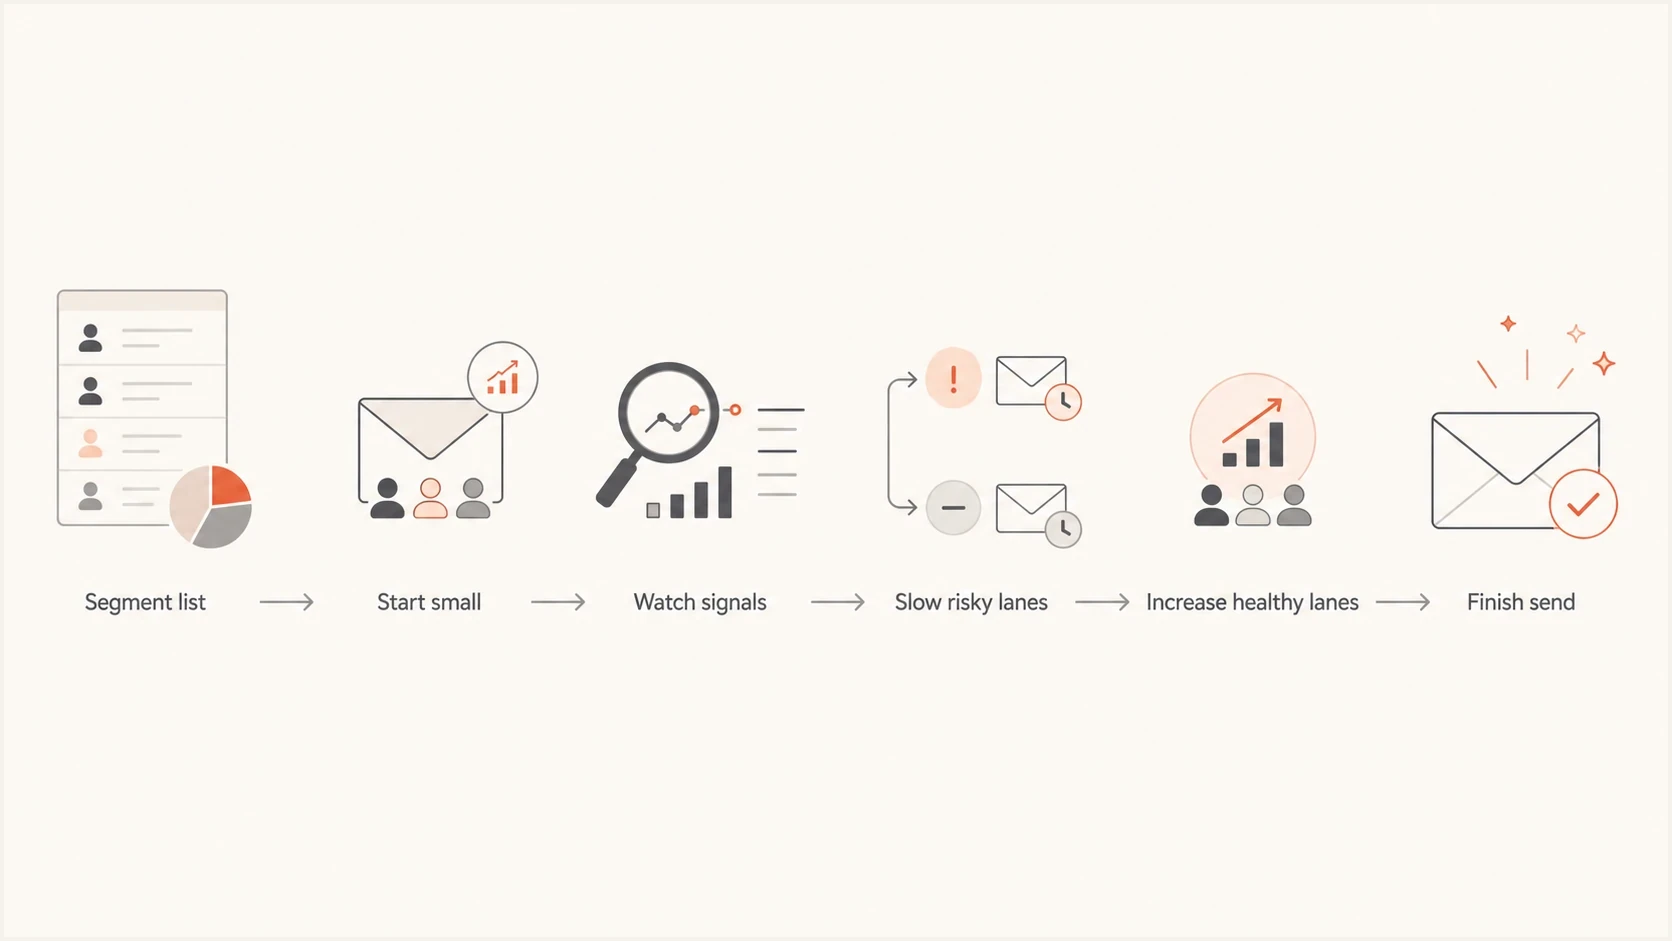
Flowchart for staggering email sends, with list segmentation, delivery monitoring, and gradual volume increases.
How to plan staggered email sends
The right pacing depends on starting reputation, list quality, mailbox-provider mix, message urgency, and recent volume. A practical default is to send first to the most engaged recipients, measure provider-specific responses, then release larger waves only where the signals stay healthy. Start deadline-driven campaigns early enough to allow for temporary deferrals and retries.
A sender with stable reputation can often move a large notice across the same day in batches. A cold IP, a new domain, an infrequent sender, or a sender that has already hit throttling needs a slower ramp across multiple days. Keep a provider-specific cap for Microsoft, Gmail, Comcast, and any domain group returning rate-limit deferrals.
Illustrative pacing plan
Initial wave: Small engaged segment within normal provider-specific hourly volume
Observe: Review SMTP replies, queue movement, complaints, and bounces
Next wave: Hold the same rate until the previous wave clears normally
Later waves: Increase gradually only where acceptance remains healthy
Pause: Any provider with repeated rate-limit deferrals or rising complaints
These waves are an example, not a fixed email warm-up schedule or mailbox-provider limits. Base each increase on the sender's normal volume and the response to the previous wave. Start lower when reputation is new, recent volume has been quiet, the list contains older recipients, or complaints are above normal.
|
|
|
|---|---|---|
Monthly batch | Several timed waves | Deferrals and queue age |
New or cold IP | Gradual daily ramp | Bounces and complaints |
Microsoft-heavy list | Provider-specific lane | 4xx rate limits |
Comcast-heavy list | Provider-specific lane | 4xx rate limits |
Use these choices as planning defaults, then adjust each lane by its SMTP response.
Do not let retries hide the real rate
A campaign can look paced at the application layer while the mail transfer layer retries aggressively underneath it. Separate planned sends from retries when reviewing throughput. Retry storms increase connection pressure and can hide the rate that receiving servers actually see.
Set sending rates across campaigns and retries
Schedule waves, then smooth the sending speed within each wave. Set an aggregate messages-per-minute cap across campaigns, sequence follow-ups, and retries that share a sending IP or domain. Stay within the email service provider's (ESP's) hourly and daily sending quotas, and use lower receiving-provider limits when SMTP responses require it. Configure SMTP connection concurrency separately because a message cap does not prevent too many simultaneous connections.
Illustrative provider-lane capacity, including retries
Total cap: 6,000 SMTP delivery attempts/hour
Reserved retry capacity: 1,200 attempts/hour
New-message capacity: 4,800 attempts/hour (80/minute)
Apply the total cap across every campaign using this lane
These figures are planning examples, not published provider limits. Count delivery attempts rather than only delivered messages, and reduce new-message throughput when retry demand rises. Reserve sending capacity for urgent password resets and receipts so a bulk campaign cannot occupy the whole queue.
Use increasing retry intervals with a small random offset (jitter), following the receiving provider's retry guidance, and keep retries within the same cap. Smooth each wave instead of releasing another burst at the top of the hour. Google's sender guidelines recommend consistent sending rates and reducing volume when messages are deferred.
How to segment the send
Staggering works best when the batches are not random. Remove unsubscribed recipients, spam complainants, and confirmed invalid addresses before scheduling promotional waves. Build eligible segments by engagement, then pace each segment by mailbox provider. This lets the early send create a useful engagement sample without treating later waves as a place for addresses that should be suppressed.
- Send to recent clickers, purchasers, account users, and reliable responders before dormant contacts.
- Group Gmail, Microsoft, Comcast, Yahoo, and hosted custom domains by receiving MX infrastructure when they share provider limits.
- Review less active opted-in contacts and previous soft bounces before later waves; suppress persistent failures and invalid addresses.
- Keep essential notices separate from promotional mail so each stream has its own pacing.
- Stagger by recipient time zone when useful, while keeping provider caps across overlapping local-time schedules.
Example staggered list mix
Illustrative mix of eligible recipients only. Add less active opted-in groups after acceptance stays stable; exclude suppressed addresses from every wave.
Recent
Moderate
Dormant
Give each provider returning rate-limit deferrals its own smaller ramp. If Microsoft delays mail after wave one while Gmail accepts it cleanly, let healthy lanes continue only when the problem is isolated to Microsoft. Hold the Microsoft lane and resume it at a lower rate after a successful test and falling deferrals, keeping queue age under review.
Signals to watch during the send
The point of staggering is control, so monitor acceptance and recipient response while the send is running. Prioritise provider-specific SMTP replies, queue depth, retry age, hard bounces, complaint rate, placement, and meaningful click or reply activity. Treat open data as directional because image blocking and privacy protections distort it. SMTP acceptance means the receiving server took responsibility for the message; it does not prove inbox placement. Review delayed complaint data before committing to the next day's increase.
Before the full run, send the real message through Suped's email tester and review authentication, DNS, blocklist (blacklist) results, TLS, and unsubscribe headers. Suped's tester checks the received message and sending setup; it does not predict inbox placement or score spam content. That does not replace live campaign monitoring, but it catches obvious mistakes before volume magnifies them.
Email tester
Send a real email to this address. Suped shows a results button when the test is ready.
?/43tests passed
Deferral trend response
Compare each provider lane with its own baseline and the response to the previous wave.
Healthy
Normal for this lane
Continue the planned ramp while complaints, bounces, retry age, and queue age remain stable.
Caution
Above baseline
Hold the next increase and extend the observation period before another wave.
Stop
Persistent or rising
Pause that provider lane, lower retry pressure, and investigate the SMTP replies.
No universal deferral percentage works across every provider and sender. A change from the lane's normal response matters more than an isolated number. Repeated rate-limit replies while volume rises mean the receiving side is asking for less pressure.
When throttling starts, avoid broad changes made in panic. First cap the affected provider, reduce retry concurrency, and compare the affected recipients with earlier waves. If the problem is concentrated in older users or one provider, use a narrow response instead of stopping every healthy lane.
Authentication and reputation checks
Staggering cannot compensate for broken SPF, DKIM, DMARC, TLS, reverse DNS, or a poor reputation signal. When a campaign is throttled after a spike, check authentication first with a domain health checker, then compare the results with the provider that is delaying mail.
For personal Gmail accounts, bulk senders need SPF and DKIM, a DMARC record with at least p=none, DMARC alignment, TLS, valid forward and reverse DNS, and one-click unsubscribe for marketing or subscribed messages. Google's sender guidelines recommend a user-reported spam rate below 0.1% and avoiding 0.3% or higher. Pacing does not override these requirements.
Suped's product supports this workflow by bringing DMARC monitoring, SPF and DKIM visibility, sending-source data, authentication alerts, and blocklist monitoring into one view. During a ramp, a team can compare reported authentication failures or blocklist (blacklist) events with the affected sending source and its SMTP logs.
Issues page showing top issues, verified sources, unverified sources, and authentication pass rates
Where Suped fits
Suped surfaces authentication failures and sending-source changes when reports arrive, alongside DNS checks and blocklist (blacklist) monitoring. DMARC aggregate reports are usually daily, as described in RFC 9990, so they cannot control a live ramp minute by minute. Use SMTP logs for immediate rate decisions and Suped's report history to investigate authentication changes.
Keep the diagnosis specific. Fix an SPF failure as an SPF problem. Restore DKIM for the affected sender when its signature is missing. If a blacklist listing matches the affected sending source, investigate the listing and receiving provider's response before resuming that source. Staggering is the pacing layer of the delivery workflow.
How to confirm throttling in SMTP logs
A slow campaign is not proof of reputation-based throttling. Confirm the cause in SMTP responses and queue logs before changing the send. A 4xx reply is temporary, so the sending mail server normally queues the message and retries later. A 5xx reply is a permanent failure for that delivery attempt and should not be retried as though it were a throttle.
|
|
|
|---|---|---|
Repeated 421 or 451 rate-limit replies | Receiving provider is temporarily limiting the source | Slow that provider lane and reduce retry pressure |
4xx mailbox or system reply | Temporary recipient or infrastructure condition | Retry normally and avoid blaming reputation without more evidence |
Messages waiting before an SMTP attempt | Application or sending-platform limit | Check the outbound scheduler and internal queue |
5xx rejection | Permanent policy, address, authentication, or routing failure | Follow the response text and do not keep retrying that delivery |
Use the full SMTP response text because the enhanced status code alone does not always identify the cause.
Group responses by receiving MX provider, recipient domain, enhanced status code, sending IP, and time window. Look for repeated rate-limit wording or a rising share of 4xx replies as volume increases. Mailbox-full replies, temporary system errors, DNS timeouts, and application-side caps can all create delays without proving a sender-reputation problem. A policy-related 5xx rejection does not mean the address is invalid; suppress confirmed invalid-recipient failures and fix policy failures at their source.
What to do when a provider throttles
A throttled provider lane needs a controlled response. Do not keep pushing until the queue clears, because repeated pressure ignores the receiving provider's request to slow down. Treat the deferral as operational feedback and lower pressure immediately.
- Stop raising volume for the affected provider while other healthy lanes continue.
- Lower connections, messages per connection, recipient throughput, and retry pressure for that domain group.
- Check whether the wave contained dormant users, stale addresses, unverified contacts, or prior soft bounces.
- After the provider's retry interval, test at a lower cap and increase only as acceptance improves and the backlog drains.
Provider-specific throttling can follow long quiet periods followed by large sends. Monthly mail is harder to pace when a large campaign exceeds the sender's recent accepted volume. Splitting the monthly send into paced waves reduces the immediate spike, but there is no fixed interval after which an IP or domain becomes 'cold'.
If Microsoft domains are the problem, slow that lane first and keep the rest of the campaign separate. If several large providers throttle at the same time, treat it as a broader sender issue and review list quality, complaints, authentication, recent volume, and email throttling and delays before sending more.
Views from the trenches
Best practices
Start with engaged recipients, then expand only after provider signals stay stable.
Separate major providers into lanes so one throttled group does not slow all mail.
Keep retry pressure low when deferrals rise, then resume from a smaller volume cap.
Common pitfalls
Calling mail transactional does not prevent complaints or invalid-recipient failures.
A monthly campaign can exceed recent accepted volume even when previous sends worked well.
Random batches mix dormant users with active users and make early signals harder to read.
Expert tips
Split required notices across days when the deadline allows provider-specific pacing.
Watch Microsoft-heavy segments closely because quiet periods can make spikes harder.
Use consent, provider responses, engagement and prior bounce history to order each wave.
Marketer view
Marketer from Email Geeks says recipient engagement drives reputation more than the internal label a sender gives the message.
2025-02-27 - Email Geeks
Marketer view
Marketer from Email Geeks says spreading a send across time can show steadier activity and avoid a sudden IP spike.
2025-02-27 - Email Geeks




