Exchange Online mailbox quarantine incident blocks email delivery
News
Updated on 25 Sep 2026: We updated this guide with the incident's historical status, trace-retention limits, and safer recovery guidance.
Microsoft tracked EX1436407 as an Exchange Online incident that incorrectly placed some mailboxes into service-level quarantine beginning July 19, 2026. The condition blocked inbound email to affected mailboxes, and internal or external senders could receive non-delivery reports (NDRs).
The latest update verifiable in public reporting was dated July 23 at 20:30 UTC. It said data cleanup was progressing and Microsoft was removing affected mailboxes from quarantine in processed regions. Microsoft expected the work to finish by a planned July 24 checkpoint, but that forecast was not a resolution notice. No later final notice was available in the public sources reviewed, which does not mean the incident remains active. Affected administrators should use their tenant-specific incident history to confirm the final state.
Incident record and status verification
The authoritative record for affected administrators is the Microsoft 365 Service Health incident. It can show tenant-specific scope and closure details that public status pages do not expose. Public reporting on EX1436407 confirms the mailbox quarantine behavior, reported cause, and remediation progress through July 23.
How to verify the final state
Open EX1436407 in the Microsoft 365 admin center and review the tenant's incident history. The last publicly verifiable update described remediation in progress, so a public article cannot establish the final tenant-specific recovery time. If related failures continue, compare current message traces and NDRs with the incident window instead of assuming the July incident is still active.
|
|
|
|---|---|---|
Incident start | Jul 19, 22:00 | Official impact start |
Publicly reported update | Jul 23, 20:30 | Cleanup progressing |
Planned checkpoint | Jul 24, 19:00 | Forecast, not resolution proof |
Times are UTC and follow Microsoft's incident notices available in public reporting.
The incident affected Exchange Online tenants, users waiting for mail, and external senders delivering to quarantined mailboxes. Microsoft did not publicly disclose the affected regions or customer count. Impact varied by region and mailbox, so one successful delivery in a tenant did not prove that every mailbox had recovered.
What Microsoft says happened
Microsoft linked EX1436407 to a recent infrastructure change. Unexpected indexing data drove excessive memory use, and the resulting out-of-memory condition caused Exchange Online to quarantine mailboxes incorrectly. Public reporting identified EX1436407 as a recurrence of earlier incident EX1434354, which required additional remediation work.
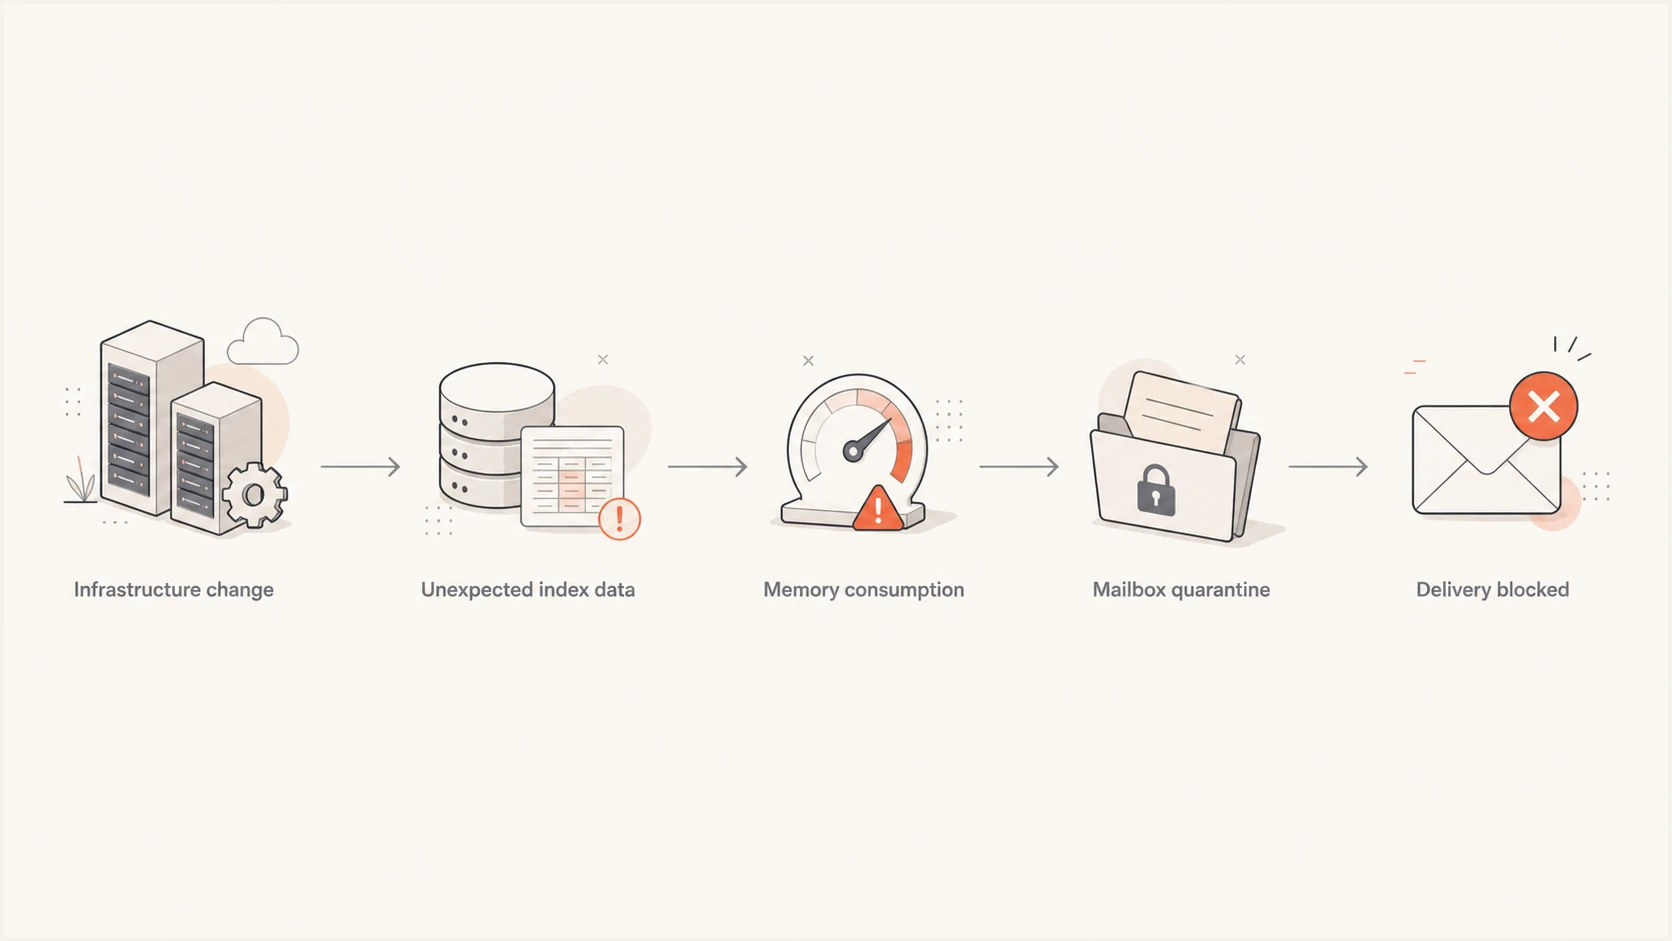
Flow of EX1436407 from infrastructure change to blocked delivery
Public reporting said cleanup of excess indexing data moved from 66% to 72% during July 23. Microsoft released mailboxes after validating memory levels in each processed region. Those percentages documented interim progress, not full recovery.
This was different from normal message quarantine. Under a security verdict, Exchange Online isolates a particular message because of spam, malware, phishing, or policy. In EX1436407, Microsoft said the mailbox itself was incorrectly quarantined by the service. Administrators should not expect every related failure to appear in the ordinary message quarantine interface.
That distinction explains the broad symptom pattern. Multiple unrelated senders could fail against the same recipient mailbox even when their messages authenticated correctly. Public reporting also described problems with sending and calendar access for some users, while the incident notice identified blocked receipt and NDRs as the mail-flow impact.
How email operators should investigate related failures
Treat a sudden, correlated rise in Exchange Online NDRs as an incident dataset before treating it as a list-quality event. Preserve evidence first, separate temporary service impact from permanent recipient failures, and change suppression only after recipient-level evidence supports it.
- Preserve evidence. Store the full NDR, enhanced status code, diagnostic text, reporting server, recipient, original message ID, and UTC timestamps. Do not keep only a dashboard label such as hard bounce.
- Check Service Health. Review EX1436407 in the affected tenant and record the incident history. Tenant notices have more operational value than assumptions based on one sender's results.
- Run message trace. Trace representative messages by recipient and a narrow UTC window. Compare failed recipients with successful recipients in the same tenant and region where known.
- Protect list state. Place incident-correlated failures in a temporary hold. Do not convert a broad spike into permanent invalid-recipient suppression without recipient-level proof.
- Control retries. Keep standards-based retries for temporary failures. Pause aggressive application retries that create duplicate traffic, then test a small sample when tenant status indicates recovery.
- Avoid destructive workarounds. Do not recreate mailboxes, toggle licenses, or make unrelated transport changes to clear a service-side condition.
- Inform stakeholders. Give support and business teams the incident ID, affected time window, known symptoms, and current tenant status.
Exchange Online administrators can use message trace in the admin interface or the V2 Exchange Online PowerShell cmdlets. Get-MessageTraceV2 searches up to the last 90 days, and each query can cover no more than 10 days. Export incident evidence before it ages out, and keep queries narrow because a focused recipient and time window makes the pattern easier to read.
Exchange Online message trace examplePowerShell
$start = Get-Date "2026-07-23 00:00:00Z"
$end = Get-Date "2026-07-24 00:00:00Z"
$recipient = "user@example.com"

$trace = Get-MessageTraceV2 `
  -RecipientAddress $recipient `
  -StartDate $start `
  -EndDate $end `
  -ResultSize 5000

$trace | Get-MessageTraceDetailV2
If the trace and NDR pattern is unclear, use a controlled message through the email tester to retain a known test result. Do not flood the affected mailbox. One measured test after tenant status indicates recovery has more value than repeated sends during an active service failure.
Why sender-side changes do not fix this
A recipient-side mailbox quarantine cannot be repaired by changing SPF, DKIM, DMARC, IP reputation, message content, list hygiene, or retry timing. Those controls still matter for ordinary delivery, but none removes a mailbox from Microsoft's service quarantine. Changing them while diagnosing EX1436407 can create new problems and obscure the original evidence.
Useful incident actions
- Evidence. Retain complete NDRs and trace records.
- Correlation. Group failures by provider, time, and recipient.
- Recovery. Use Service Health and controlled test evidence.
- Suppression. Use a reversible incident hold.
Changes that do not release mailboxes
- Authentication. Editing SPF, DKIM, or DMARC.
- Reputation. Rotating a sending IP or domain.
- Content. Rewriting subject lines or templates.
- Volume. Rapidly resending every failed message.
Do not try to run Disable-MailboxQuarantine against Exchange Online. Microsoft documents that cmdlet for on-premises Exchange only, so it cannot release a cloud mailbox affected by EX1436407. Removing a license or recreating a mailbox is also disproportionate and can introduce a separate recovery problem.
Authentication data is still useful as a control. If SPF and DKIM pass with DMARC alignment while Exchange Online recipients fail in the incident window, that supports a recipient-side diagnosis. A domain health check can document the sending domain's current state, but it cannot clear EX1436407.
For failure patterns outside the official incident window, follow a broader Exchange Online troubleshooting process. That investigation should separate recipient validity, policy rejection, sender reputation, authentication, and transport failures rather than forcing every NDR into the incident explanation.
How to recover without damaging list data
Recovery needs two signals: Microsoft status evidence and observed delivery evidence. A final Service Health notice is strong evidence, but tenant recovery can become visible earlier in selected regions. Conversely, a successful test to one mailbox does not prove broad recovery. Use a staged release of held traffic and watch results at each step.
Traffic recovery gates
Use evidence-based gates instead of releasing every suppressed message at once.
Active impact
Hold
Incident-correlated NDRs continue across unrelated senders or recipients.
Partial recovery
Pilot
Service updates show progress and a small controlled sample succeeds.
Stable recovery
Resume
Microsoft confirms resolution and representative delivery remains stable.
Residual failures
Investigate
Isolated recipients still fail after broad recovery and need separate review.
Start with recent, time-sensitive messages to a small, representative recipient set. Do not automatically replay expired password codes, duplicate invoices, obsolete alerts, or messages whose business action has already completed. Preserve the original relationship between campaign, recipient, message ID, and NDR so later analysis remains reliable.
Do not convert the spike into permanent suppression
A mailbox quarantined by Exchange Online can still belong to a valid recipient. Bulk-marking these addresses invalid damages future reach after service recovery. Use a reversible incident reason, preserve the NDR, and reclassify only when later evidence confirms a permanent address failure.
After normal traffic resumes, compare the Exchange Online failure rate with its pre-incident baseline. Investigate isolated permanent errors on their own terms. For example, a persistent address rejection after recovery requires analysis of the exact status code rather than continued attribution to EX1436407.
Where DMARC monitoring fits
DMARC monitoring cannot repair a quarantined Exchange Online mailbox. Its role here is diagnostic separation. Stable authentication pass rates across the incident window help show that the sending domain did not suddenly break when Microsoft 365 NDRs increased. That evidence protects teams from unnecessary DNS edits during a recipient-side service failure.
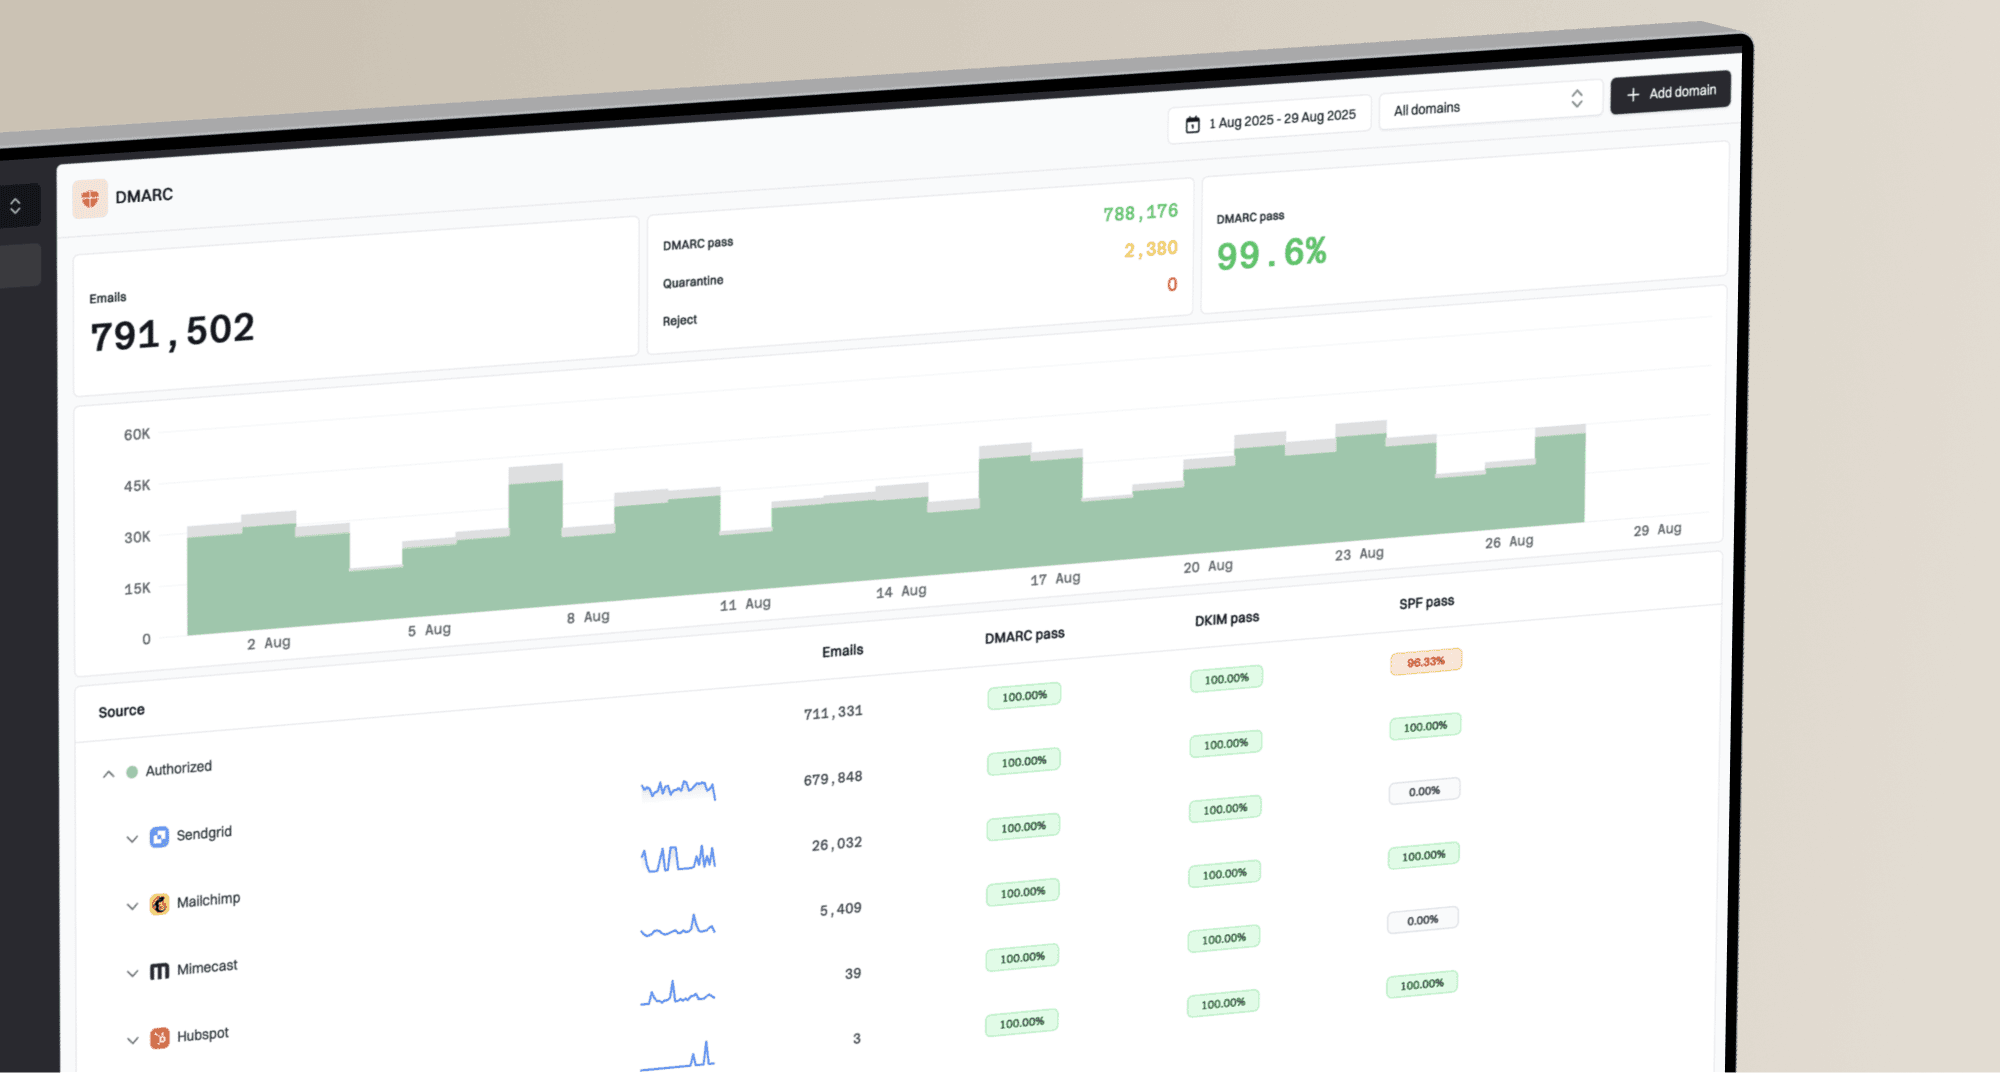
Suped DMARC dashboard showing email volume, authentication health, and source breakdown
Suped's DMARC platform tracks DMARC, SPF, and DKIM authentication over time. In this workflow, compare the source breakdown and authentication trend with the NDR timeline to verify that approved senders remained authenticated while failures concentrated at Exchange Online recipients. Alerts can also reveal a genuine sender-side change that happened during the same window.
Use DMARC monitoring to document what stayed healthy. Use Service Health and message trace for the recipient-side incident state, because authentication reports cannot confirm that Microsoft released a mailbox from service quarantine.
How to close the incident safely
EX1436407 affected Exchange Online mailbox delivery starting July 19, 2026. The last update verifiable in public reporting said cleanup was progressing and mailboxes were being released in processed regions. Because no public final notice was available in the reviewed sources, use the tenant's Service Health history to establish its resolution time.
Preserve complete NDRs, export relevant traces before the 90-day search window expires, and keep incident-correlated failures in a reversible state. Do not edit sender authentication or permanently suppress valid recipients to compensate for a mailbox condition controlled inside Exchange Online. For any residual failures, investigate the current NDR and trace evidence instead of assuming EX1436407 is still responsible.